Advancing AI Transparency and Scientific Infrastructure in 2026
New tools for interpreting autonomous systems and scaling scientific computing reshape how researchers validate and deploy AI.
Published
September 2, 2026
Reading time
2 minutes
Perspective
Research
Topics
AI interpretability · scientific computing · LLM evaluation
Recent developments highlight a dual trajectory in AI research: improving interpretability for safety-critical systems and strengthening the foundational infrastructure that enables large-scale scientific discovery. These advances signal a maturing field where transparency and accessibility are no longer secondary concerns but core requirements for credible, deployable AI.
CW-Net Enhances Autonomous Vehicle Interpretability
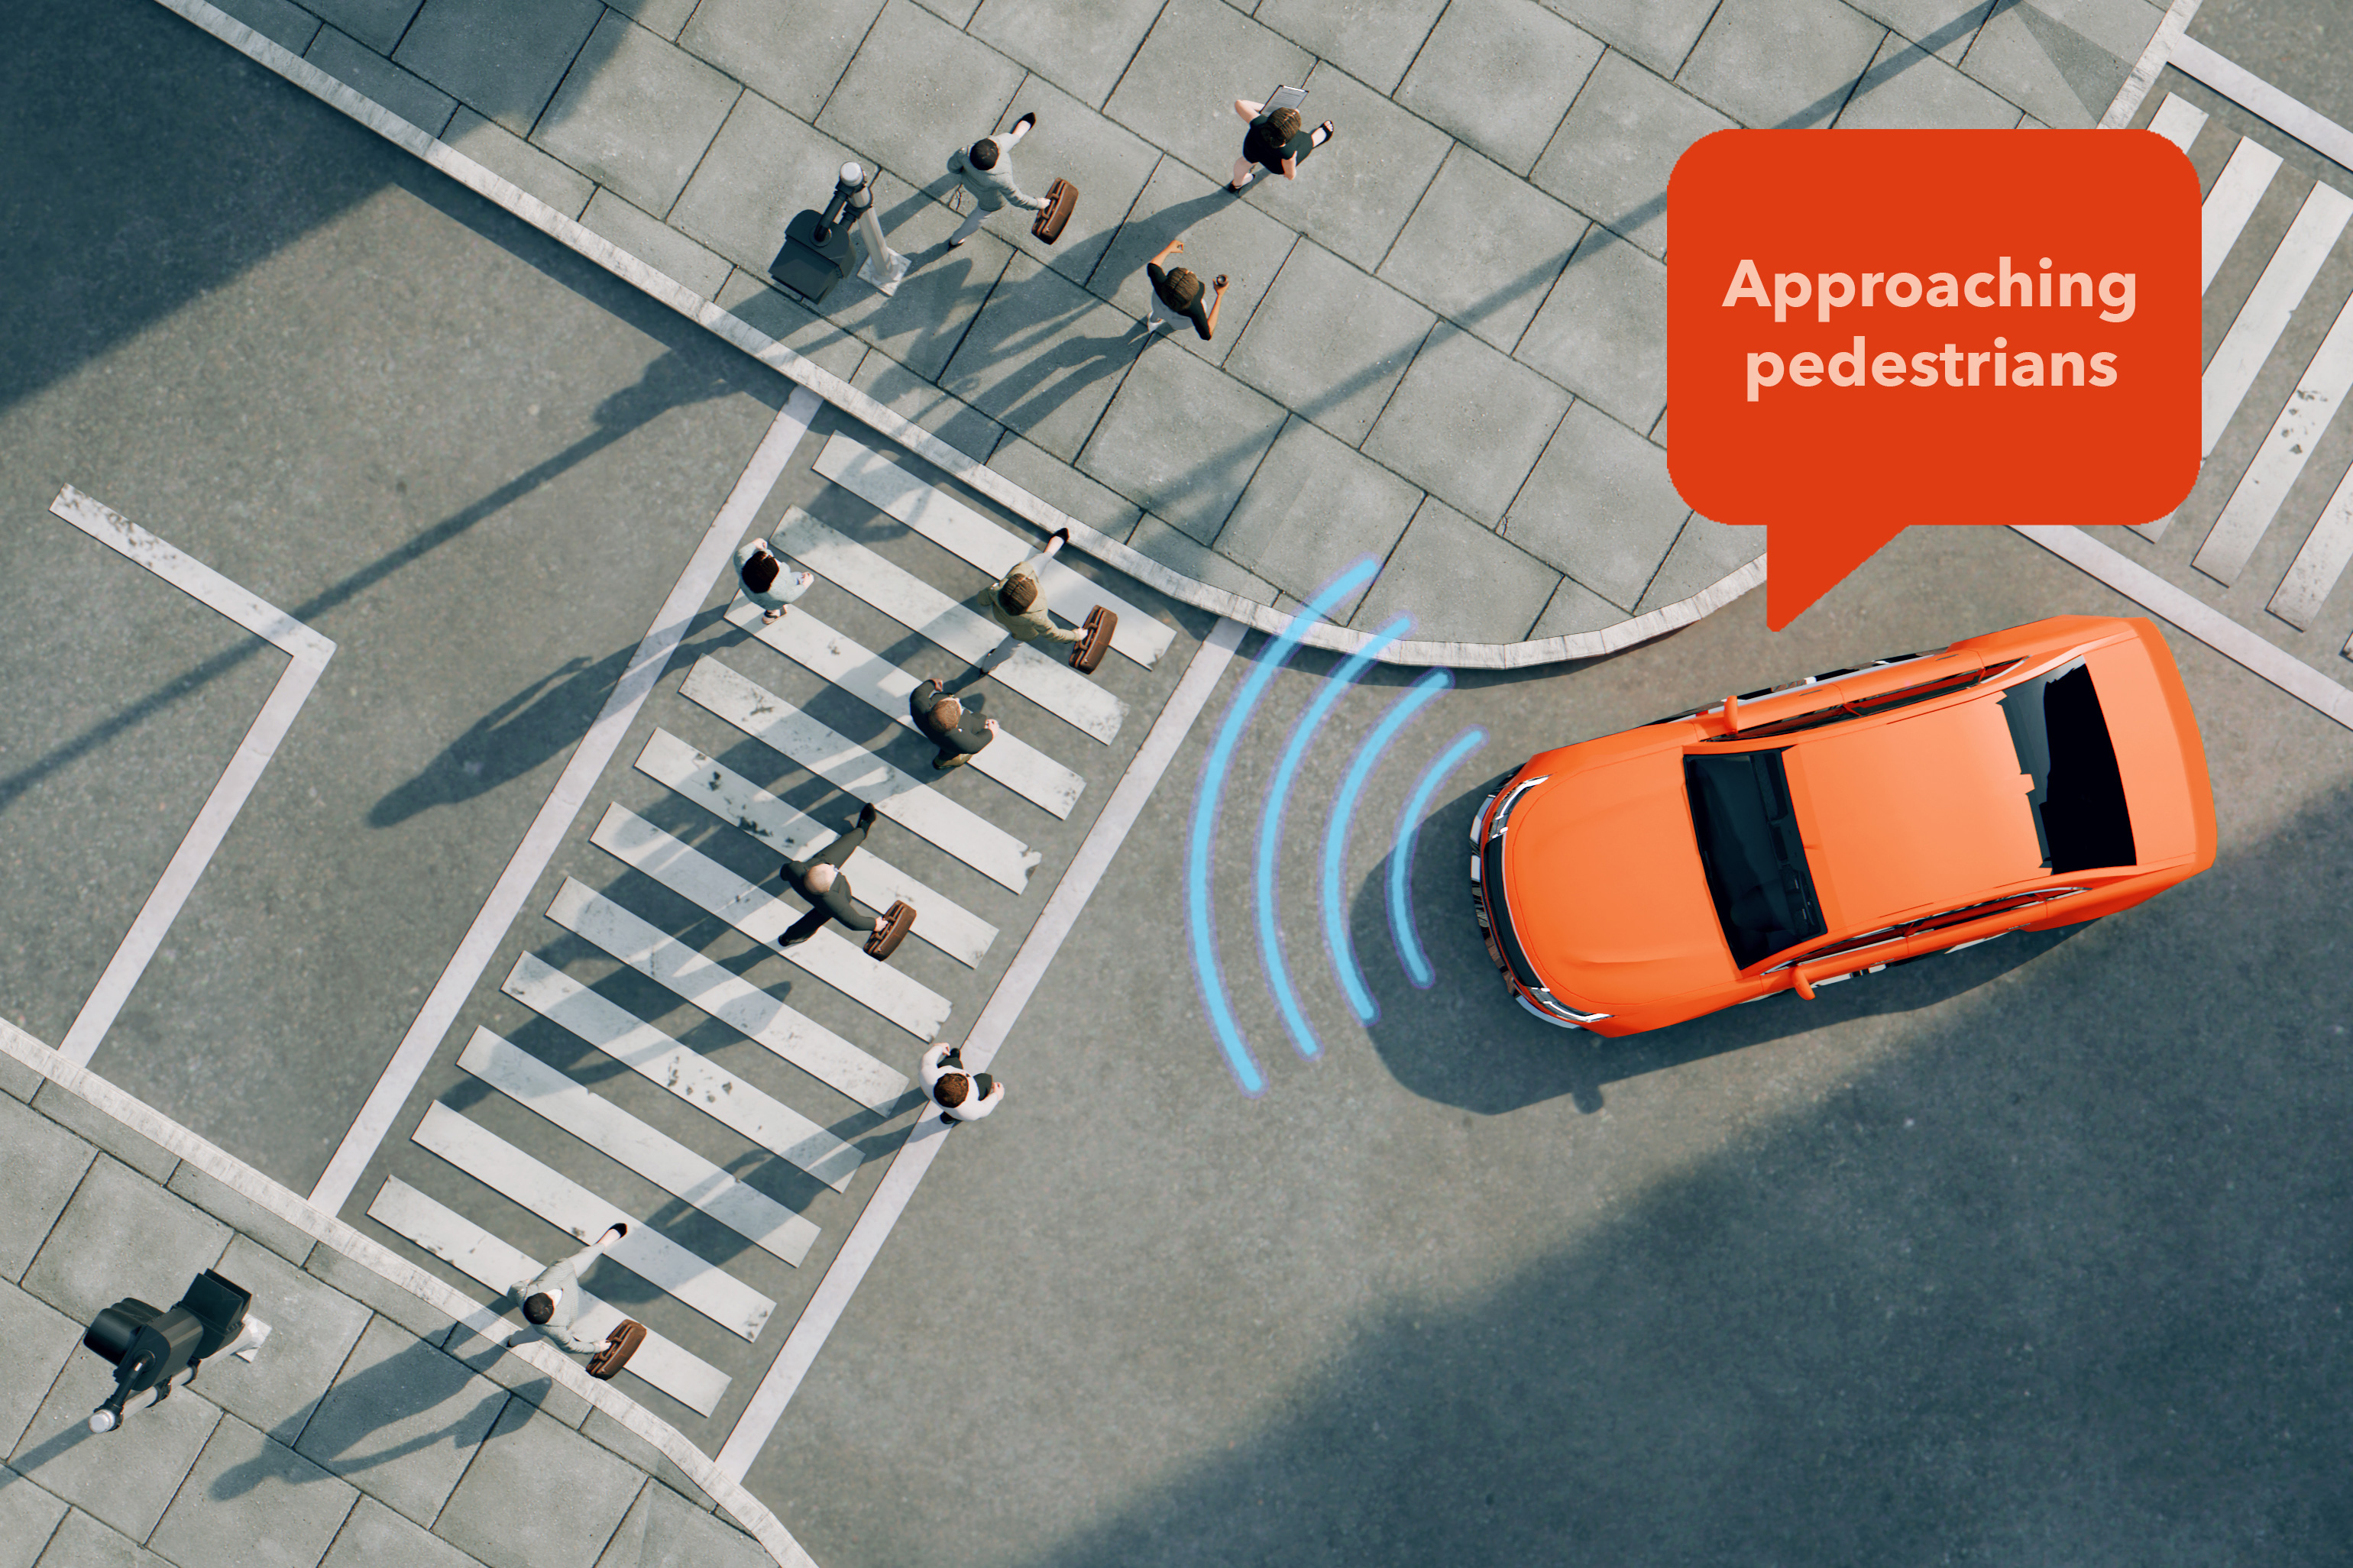
MIT’s CW-Net translates internal AI decision-making in self-driving cars into human-understandable concepts, directly addressing the black-box problem in safety-critical applications. For researchers, this means a replicable framework to audit and validate autonomous behavior without reverse-engineering model weights. This is critical for regulatory compliance and real-world deployment, shifting the burden of trust from empirical testing to explainable reasoning. The method’s public release suggests a broader trend toward standardized interpretability tooling in robotics and AI safety.
Source: System helps humans predict when self-driving cars will make mistakes · MIT News · AI
Julia’s Rise as a Scientific Computing Standard
Julia’s global adoption—used in drug design, aerospace, and energy systems—demonstrates how a purpose-built language can outpace general-purpose alternatives in scientific domains. Researchers benefit from its native support for parallel computing and symbolic mathematics, reducing the friction between prototyping and production. This signals a paradigm shift: domain-specific languages are no longer niche but essential infrastructure. The MIT endorsement validates Julia as a long-term investment for computational research teams seeking performance without sacrificing expressiveness.
Source: How an MIT research project became a global programming language · MIT News · AI
BenchMIRT Challenges LLM Evaluation Norms

Hugging Face’s BenchMIRT reveals that current LLM benchmarks often measure dataset memorization or prompt engineering skill rather than true reasoning or generalization. This is a wake-up call for researchers relying on leaderboard rankings to validate model improvements. The study urges a move toward task-specific, context-aware evaluation protocols. For practitioners, this means rethinking how they report results and design experiments—prioritizing reproducibility and ecological validity over inflated scores on standardized tests.
Source: BenchMIRT: What are LLM benchmarks actually measuring? · Hugging Face Blog
UAVid Benchmark Highlights Real-World Model Trade-offs

The comparison between CABiNet and YOLO26-sem on UAVid underscores that accuracy gains in UAV object detection often come at the cost of real-time latency and GPU efficiency. For researchers deploying models in edge environments, this is not just a technical detail—it’s a deployment constraint. The post’s presence on r/MachineLearning indicates community-driven benchmarking is filling gaps left by academic papers. This signals a growing need for transparent, hardware-aware evaluation metrics beyond mAP or F1 scores.
Source: CABiNet (ICRA 2021) vs YOLO26-sem on UAVid: accuracy, compute, and GPU latency [P] · r/MachineLearning
What to watch next
The convergence of interpretability, infrastructure, and rigorous evaluation is redefining research standards in AI. Transparency is no longer optional; it is foundational to trust, scalability, and real-world impact.
Continue reading