Multimodal Efficiency, Agent Memory, and Explainable AI Advance Research Infrastructure
Hugging Face launches efficient multimodal models and agent memory tools; MIT introduces explainable self-driving AI and quantum-AI collaboration.

Published
September 4, 2026
Reading time
3 minutes
Perspective
Research
Topics
Multimodal · Agent Memory · Explainable AI
Recent developments converge on enhancing the reliability, efficiency, and interpretability of AI systems. Foundational models are becoming more capable and resource-efficient, while tools for agent control and system transparency are emerging as critical for real-world deployment. These advances collectively shift research focus from raw performance to sustainable, auditable, and human-aligned AI.
NeoMME: Efficient Multimodal and Multilingual Encoding
Hugging Face’s NeoMME introduces a unified encoder that processes text, images, and audio in multiple languages with reduced computational overhead. This matters to researchers because it lowers the barrier to deploying multimodal systems in low-resource settings and enables more equitable cross-lingual research. Unlike prior models requiring separate encoders, NeoMME’s architecture reduces training costs and simplifies integration into existing pipelines, making it a practical foundation for future multimodal applications.
Source: NeoMME: an efficient Multimodal-native and Multilingual Encoder · Hugging Face Blog
Agent Memory Systems with User Ownership

Hugging Face’s new framework allows developers to embed persistent, user-controlled memory into AI coding agents. This is significant because it addresses a core limitation in agent autonomy: the inability to retain context across sessions without relying on cloud-based or opaque storage. Researchers can now build reproducible, privacy-aware agents for code generation and debugging, enabling more trustworthy experimentation and reducing hallucination risks in long-horizon tasks.
Source: Give Your Coding Agents a Memory You Own · Hugging Face Blog
CW-Net: Explaining Autonomous Vehicle Reasoning
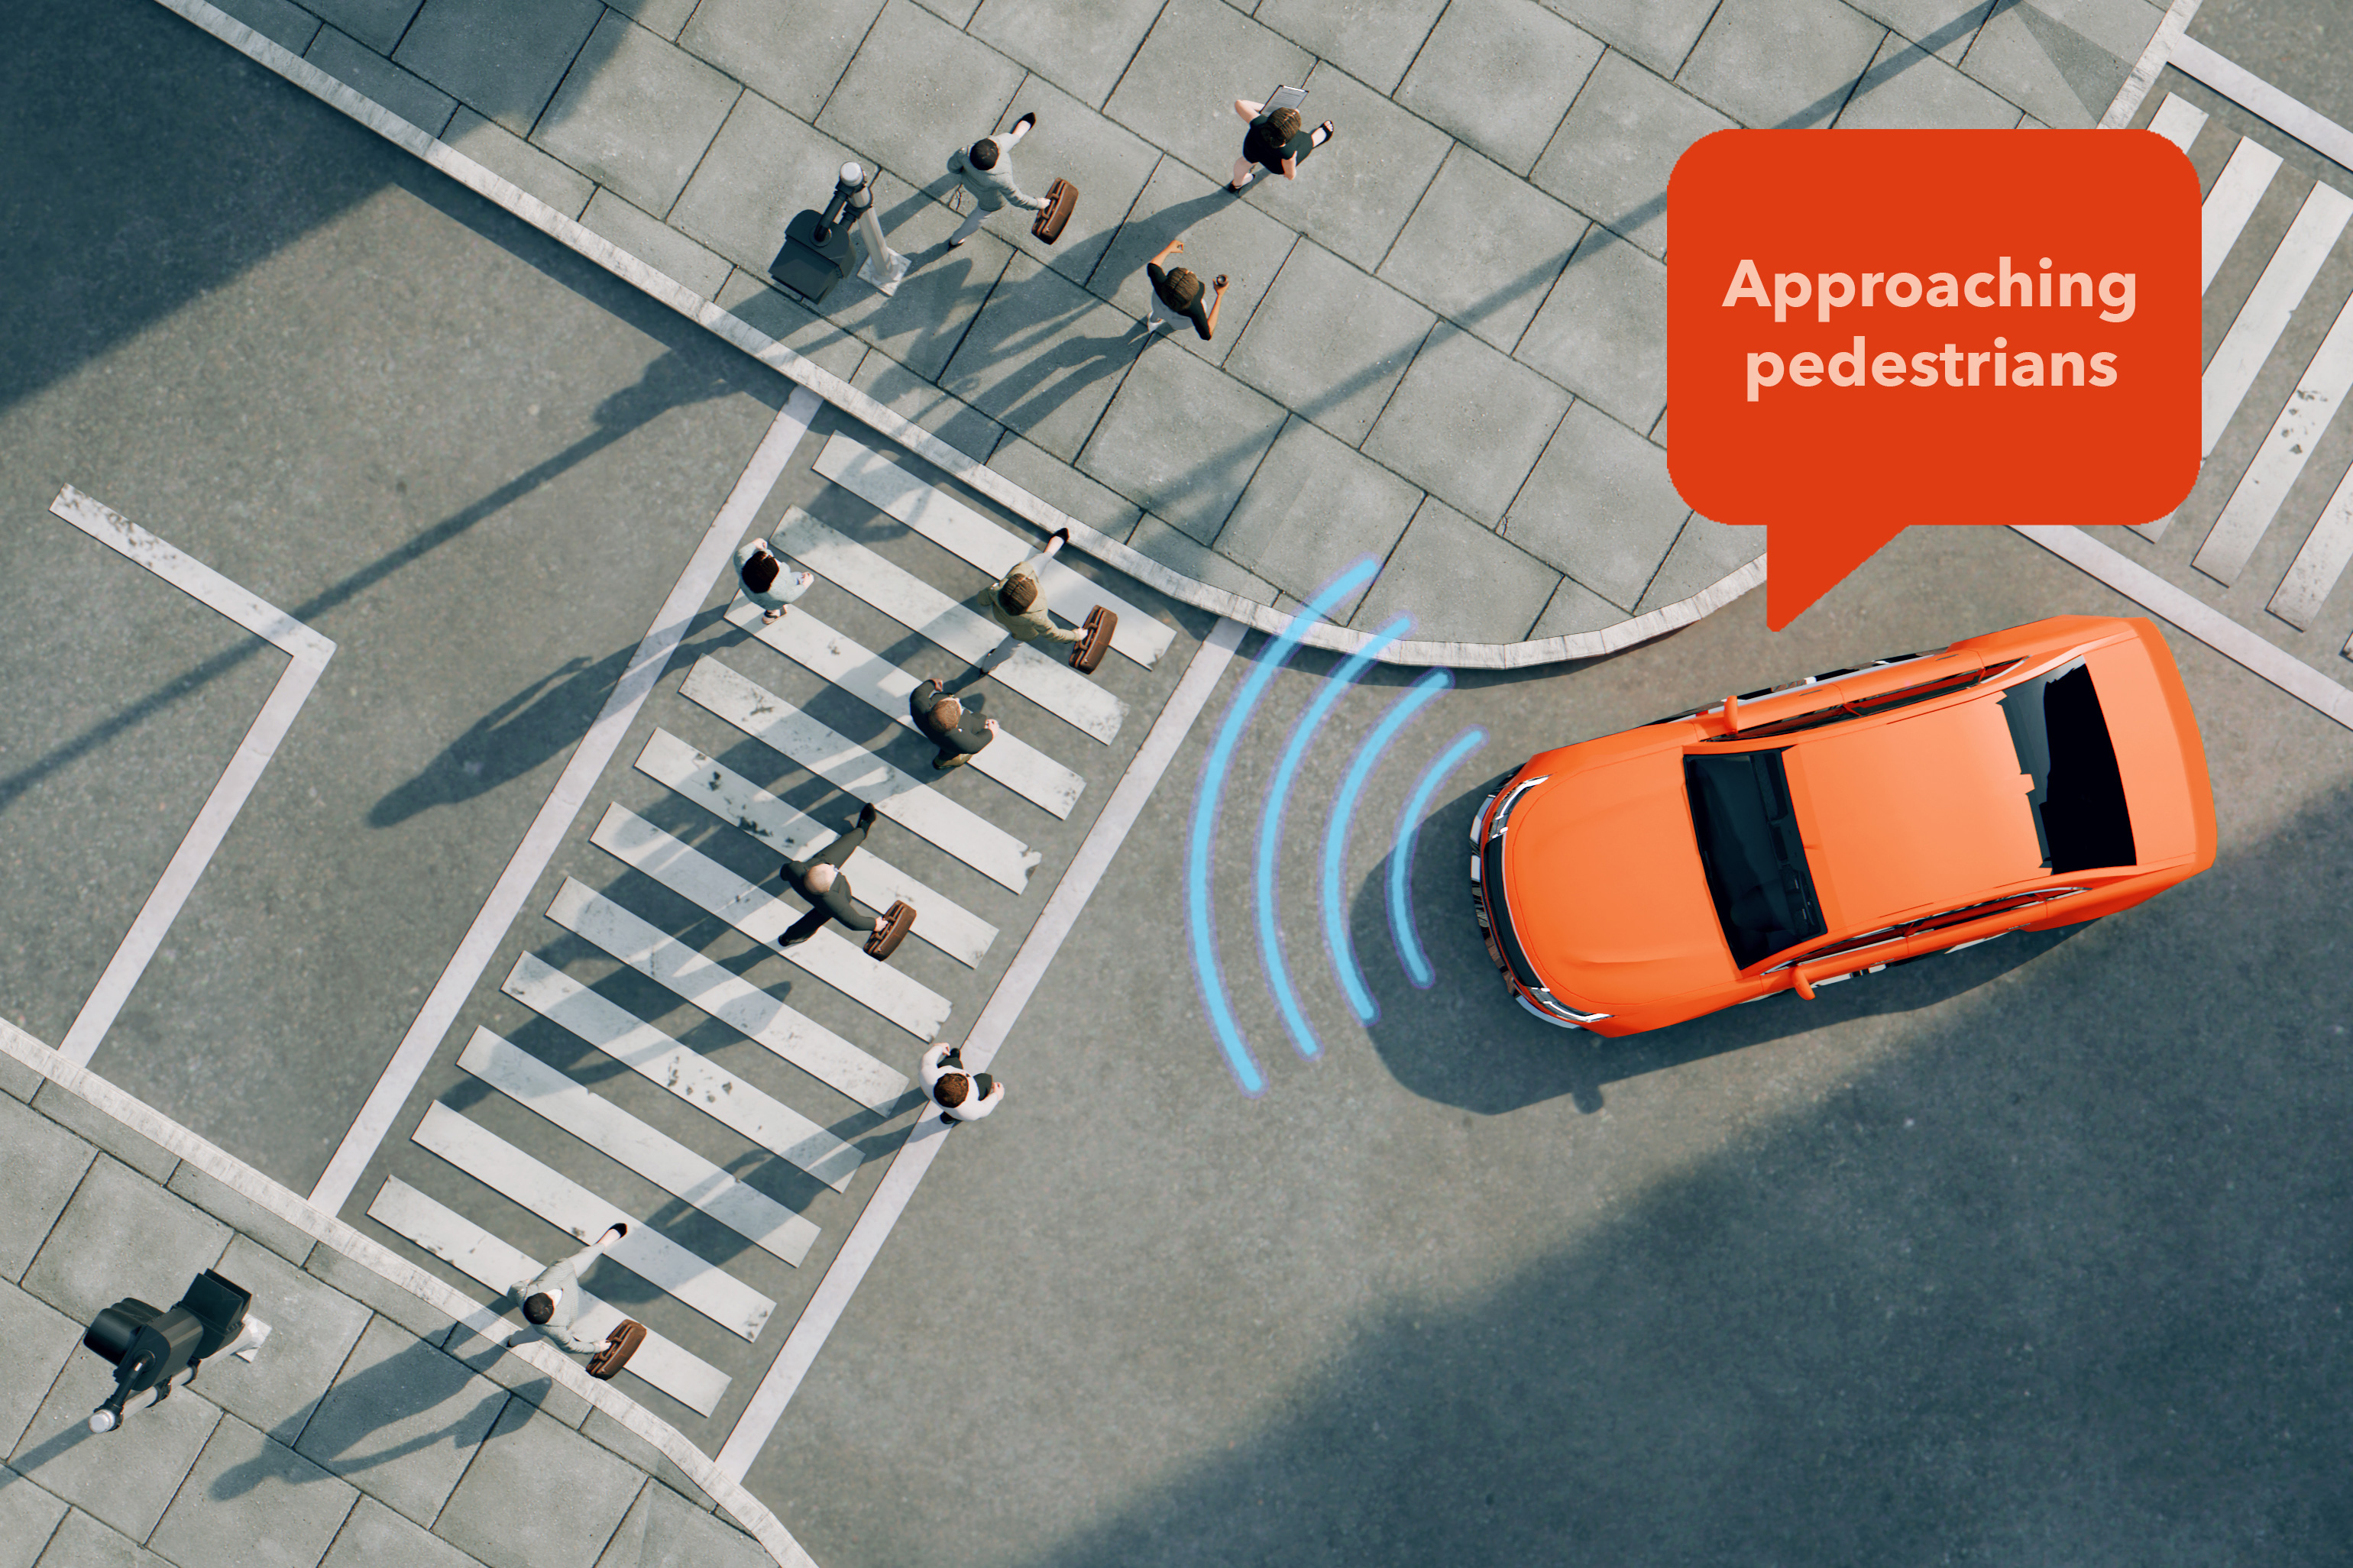
MIT’s CW-Net translates internal AI decision-making in self-driving cars into human-interpretable concepts, such as 'predicting pedestrian intent' or 'evaluating intersection risk.' This matters because it transforms black-box systems into accountable ones, enabling safety auditors and regulators to validate behavior. For researchers, it provides a template for explainability in high-stakes domains, shifting benchmarking from accuracy to interpretability and causal transparency.
Source: System helps humans predict when self-driving cars will make mistakes · MIT News · AI
MIT-IBM Quantum-AI Deployment Collaboration
The MIT-IBM Computing Research Lab is bridging theoretical quantum algorithms with practical AI deployment pipelines. This collaboration signals a maturation of quantum-AI research from proof-of-concept to production-ready integration. For researchers, it offers a model for cross-institutional translation of theory into hardware-aware software, accelerating the adoption of quantum-enhanced machine learning in real-world systems and setting new standards for interdisciplinary rigor.
Source: From MIT to IBM, expediting AI and quantum deployment · MIT News · AI
BenchMIRT: Re-evaluating LLM Benchmark Validity

Hugging Face’s BenchMIRT reveals that current LLM benchmarks often measure memorization or dataset artifacts rather than true reasoning or generalization. This is critical for researchers because it undermines confidence in model rankings and encourages redesign of evaluation protocols. The study urges adoption of dynamic, adversarial, and context-aware benchmarks, directly influencing how new models are validated and published in the community.
Source: BenchMIRT: What are LLM benchmarks actually measuring? · Hugging Face Blog
What to watch next
These developments collectively elevate the standards for AI research: efficiency, control, transparency, and validation are now as vital as performance. Researchers must prioritize systems that are not only powerful but also interpretable, sustainable, and auditable.
Continue reading